Archive Team
Abstract
Archive Team is a volunteer collective that copies websites before their owners delete them. Jason Scott started it in 2009, angry that AOL had switched off its Hometown pages with nobody keeping a copy. Its first large job was GeoCities, closed by Yahoo! in October 2009, and the method it worked out there (find the deadline, split the site into chunks, point hundreds of volunteer machines at it) has since been applied to Friendster, Tumblr, Google+, Yahoo! Answers, Imgur and billions of shortened links. The copies go to the Internet Archive. The group asks no one’s permission, and the article covers both what that has saved and what it cannot.
AOL Hometown and the Founding
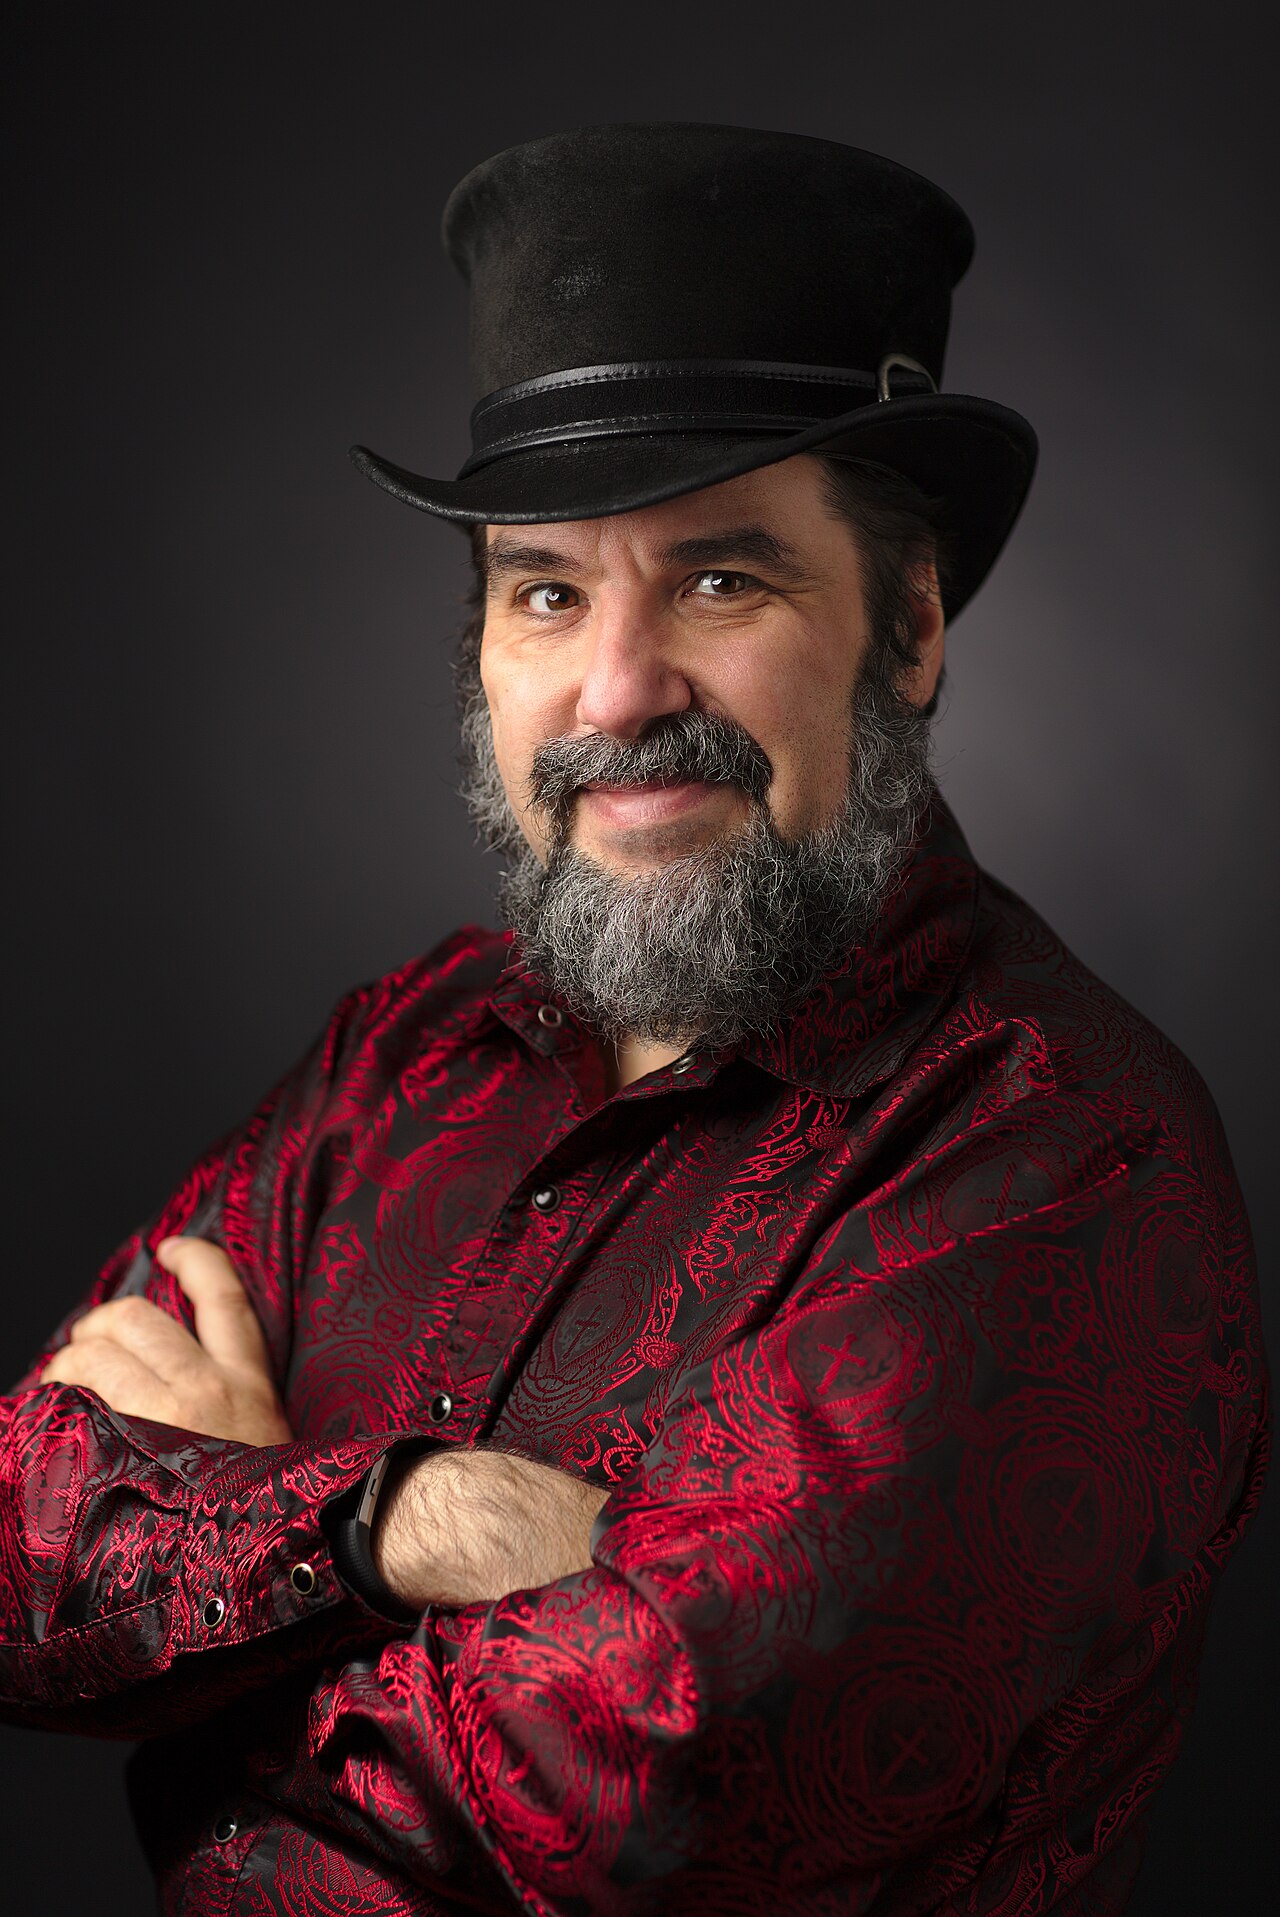
Jason Scott, born in 1970 and known online as SketchCow, collected bulletin-board text files on his site textfiles.com and released BBS: The Documentary in 2005 (see The BBS Era). On 31 October 2008 AOL shut down AOL Hometown, its free homepage service, and the pages were gone. Scott wrote on his weblog that “there ought to be a team of people who could rescue this data, who could swoop in and grab a copy before it was all gone.” Dozens of readers offered to help, and the group formed at archiveteam.org in 2009.
Scott later described the motive plainly: “Archive Team was started out of anger and a feeling of powerlessness, this feeling that we were letting companies decide for us what was going to survive and what was going to die.” The group also declined to judge what was worth keeping. In Scott’s words, “it’s not our job to figure out what’s valuable, to figure out what’s meaningful. We work by three virtues: rage, paranoia, and kleptomania.”
GeoCities
In April 2009 Yahoo! announced that GeoCities would close. The announcement, Scott wrote, was “a side mention of it in a FAQ answer buried in the support pages.” GeoCities had hosted free homepages since 1994, and Yahoo! had bought it in 1999 (see Dead End: Yahoo!).
For six months Archive Team downloaded as much as it could reach. Scott’s account from February 2011 speaks of “dozens of people on hundreds of IPs, imitating other search engines and utilizing a whole bunch of tricks.” The site went dark on 26 October 2009. Five days later Scott reported that the parallel efforts, some 60 to 80 known participants across five projects, had saved “over one million accounts,” very likely including “every major outward-facing geocities account”, meaning every page that turned up in links or search engines. Some people recovered pages of their own that they had given up for lost.
On 26 October 2010, the first anniversary of the shutdown, the group released the salvage as a BitTorrent download of about 650 gigabytes compressed (see Bram Cohen and BitTorrent). Scott called GeoCities “one of the largest-scale folk-art installations to exist in the history of the world” and argued that “websites and hosting services should not be ‘fads’ any more than forests and cities should be fads.” The torrent later became raw material for artists and historians of the amateur web (see Link Rot and the Digital Dark Age).
Friendster and the Warrior
The next years brought a steady run of closures. Yahoo! Video closed on 15 March 2011; Archive Team expected to pull about 25 terabytes from it. On 25 April 2011 Friendster, which had claimed some 115 million registered users, announced that user content would be removed by 31 May. The group wrote a script called BFF (“Best Friends Forever”) and asked for volunteers with a Unix machine and 100 GB of free disk; each instance fetched about 115 profiles an hour, and volunteers signed up for numbered ranges of profile IDs on a shared sheet.
Signing up for ranges by hand did not scale. In 2012 the group packaged its tooling as the ArchiveTeam Warrior, a virtual machine image first posted to the Internet Archive on 3 April 2012 that anyone could start in VirtualBox or VMware. The Warrior asks a central tracker for work items, downloads them, and uploads the results to Archive Team’s staging servers, from which they go to the Internet Archive and its Wayback Machine (see Brewster Kahle and the Internet Archive). The tracker keeps public leaderboards per project, which turned an archiving job into something volunteers compete at. Later versions run as Docker containers.
Tumblr and Google+
The Warrior showed what it could do when a deadline was short. Tumblr announced in early December 2018 that it would hide all adult content from 17 December. Within that fortnight archivists saved more than 320,000 Tumblr accounts, over 46 terabytes, although Tumblr blocked the IP addresses of “swaths of Archive Team’s archivists,” as Scott put it. The journalist Ernie Smith pointed out that from the server’s side “archival activity functions not all that dissimilar to a DDOS attack.”
Google+ was scheduled to close on 2 April 2019 (see Dead End: Google+). By mid-March Archive Team had downloaded more than 360 terabytes; a press release of 28 March counted about 700 volunteers pulling data at roughly 7.5 gigabits per second, with the project “only roughly 60% complete” and an estimated 85 percent of the indexed content expected by the deadline.
URLTeam and ArchiveBot
Two standing projects run between the emergencies. URLTeam copies the tables of URL shorteners, which it described as “a ticking timebomb. If they go away, get hacked, or sell out, millions of links will be lost.” Its goo.gl effort began on 4 March 2011 and was throttled by Google for years. Google announced the deprecation of goo.gl on 30 March 2018 and a final shutdown in July 2024; on 25 August 2025 the links stopped resolving, except those that had still been in use in late 2024 (see Killed by Google). Archive Team reports saving 3.75 billion goo.gl links before the cut.
ArchiveBot takes single sites on request. A volunteer types a URL into an IRC channel, and crawler nodes run by other volunteers fetch everything below it into WARC files, the standard web-archive format, which are then passed to the Internet Archive. It is used when a small site announces its closure or changes its policies. Separately, the Warrior’s long-running general URLs project held more than 22 petabytes as of 17 September 2026.
Imgur and Later Projects
The pattern continued in the 2020s. Yahoo! Answers went read-only on 20 April 2021 and closed on 4 May; the wiki records it as only partially saved. In April 2023 Imgur announced that from 15 May it would delete explicit images and images uploaded without an account, about a billion files, many of them embedded in old forum and Reddit posts. On the day of the deadline volunteers had saved more than 900 million. Reddit’s API restrictions of June 2023, Ukrainian websites after the Russian invasion of 2022, Telegram channels and YouTube became ongoing projects. The group’s Deathwatch wiki page lists announced shutdowns months ahead.
What Gets Lost
Archive Team works without permission. “Archive team doesn’t ask,” Scott said in 2011. “It takes. It takes and it dupes and it saves.” Speed is the method, and it has costs. A crawler sees only what is public and linked, so private messages, pages behind a login and anything deleted before the announcement are out of reach; the GeoCities rescue caught the outward-facing accounts and missed an unknown share of the rest. When a site throttles or blocks the crawlers, as goo.gl did for years and Tumblr did in 2018, the download stops. Yahoo! Answers announced its closure a month ahead, and the copy is still incomplete. Infrastructure fails too: an ArchiveBot incident in 2018 and 2019 lost about 6.8 TiB of downloads.
The archived data also sits with a single institution, the Internet Archive, and some of it, including the Yahoo! Answers collection, is not publicly accessible. People whose old pages were copied had no say in it. The group accepts removal requests, as it did for Google+, but otherwise holds that deciding what future historians may want is not its job.
📚 Sources
- Archive Team (Wikipedia)
- Archiveteam wiki: Main Page
- Jason Scott (Wikipedia)
- AOL Hometown (Wikipedia)
- Jason Scott: “The Splendiferous Story of Archive Team”, ASCII, 30 March 2011
- Jason Scott: “Geocities Saved!”, ASCII, 31 October 2009
- Jason Scott: “Archiveteam! The Geocities Torrent”, ASCII, 26 October 2010
- Archiveteam wiki: GeoCities
- Archiveteam wiki: Friendster
- Archiveteam wiki: ArchiveTeam Warrior
- ArchiveTeam Warrior (Internet Archive item, added 3 April 2012)
- Vice: “Archivists Say Tumblr IP Banned Them For Trying to Preserve Adult Content”, 19 December 2018
- Archiveteam press release: Help archive Google+, 28 March 2019
- Android Police: “The Internet Archive is saving Google+ data before it vanishes in a few weeks”, 18 March 2019
- Archiveteam wiki: URLTeam
- Archiveteam wiki: goo.gl
- GIGAZINE: “ArchiveTeam has completed archiving all links of the shortened URL goo.gl”, 19 August 2025
- Archiveteam wiki: ArchiveBot
- Archiveteam wiki: Yahoo! Answers
- Vice: “Archive Team Races to Save a Billion Imgur Files Before Porn Deletion Apocalypse”, 15 May 2023
- Archiveteam wiki: Deathwatch
- Image: Jason Scott (2017 Portrait) by Dennis van Zuijlekom, CC BY-SA 2.0, via Wikimedia Commons